

3·
13 days agoI’m okay with the downvotes. There’s a stronger anti-AI sentiment now than even just a month ago, and on the whole I think that’s going to be a good thing.
I’m okay with the downvotes. There’s a stronger anti-AI sentiment now than even just a month ago, and on the whole I think that’s going to be a good thing.
Yes, it was released in March. One important point is that these results are based on the semi-private test set. Perhaps it’s best to wait until it is measured against the fully private test set, but that might not happen for months.
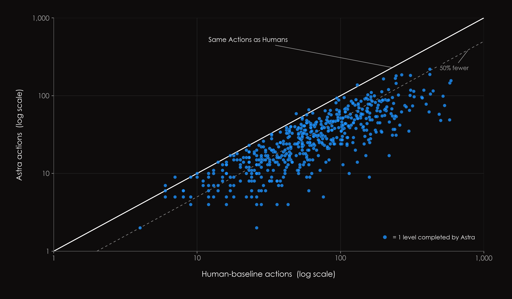
I agree with most of this. I’ve also said in the past that LLMs cannot think, and I think that’s still true for most models. The reason ARC-AGI-3 is interesting is that it was specifically designed to test reasoning, adaptability, novel problem solving, planning, memory, etc. So it was a surprise to me that Astra was able to defeat it so effectively, and that Astra invents algebras for each novel task.
But I agree we can’t trust OpenAI if these results are self-reported, and we may not be able to trust the ARC Prize Foundation fully either. Extraordinary claims require extraordinary evidence, so we need replication, transparency, and proper open science to confirm things.
I also agree with ARC Prize’s conclusion, that there are still capabilities any AI system would need to demonstrate before we can claim a full general intelligence.
I guess this is being down-voted just because it feels pro-AI. Believe me I get it, you can look at my anti-AI post history. But I think it’s important to also keep an eye out for real signals towards general intelligence, which is why I wanted to share this. I’m not celebrating it, just bringing awareness.

They basically pass the buck to the individual developer without taking any responsibility themselves.
Debian acknowledges that the legal status of material produced by generative AI systems remains the subject of ongoing discussion in many jurisdictions, including questions relating to copyright, authorship, licensing, and potential reproduction of training material.
The responsibility for every contribution rests with the contributor who submits it, who remains accountable for its technical quality, legal acceptability, and suitability for inclusion in Debian.
“It may be illegal or against FOSS, but that’s up to you to decide, good luck I guess”
Oof, they’re going to be in a whole lot of pain after the burst. Hopefully they can reverse course mid-way.
Bernie has good intentions, but he was AI-pilled by Geoffrey Hinton, who ironically also has good intentions. However, they are both out of touch with reality.
I’m confident enough about this that I’ve registered a prediction on Long Bets.
“No LLM-based AI will surpass 70% on the ARC-AGI-3 leaderboard, with a cost of $1000 or less, before June 2028.” - https://longbets.org/973/
I’m curious if you’d really disagree with the premise, and would you (or anyone here on Lemmy) be willing to put money down to challenge the bet? (Long Bets always donates any winnings to a registered non-profit of the winner’s choice, though it’s a $200 minimum).
Are you saying that LLMs can currently reason? How do you explain their low score on ARC-AGI-3? Do you think Transformer LLM architectures will be capable of reasoning within the next two years without some new breakthrough? What mechanism in the architecture allows them to reason?
Companies are only shooting themselves in the foot in the long term if they stop hiring junior engineers, and most of that work is not being replaced, it’s being shifted to the senior engineers who now have to babysit AIs that can’t actually do the job for any extended period of time. If you’re accepting AI code into a codebase without thorough review, then you’re also shooting yourself in the foot in the long term, because even the senior engineers won’t know the codebase after a while. If you’re doing thorough reviews in order to catch the AI bugs, well then you’re probably better off coding it yourself correctly in the first place, unless you’ve already allowed your skills to atrophy.
Do you really think AIs are reasoning when you ask them to troubleshoot technical issues? You may be lucky if the issue is already in their training data, but anything even slightly novel, and the AI is just going to bullshit an answer, and I guess you’re going to follow it blindly, since you don’t know enough to come up with an answer yourself.
Besides all that, how is open source AI going to stop junior developers from losing their jobs?
The word “intelligence” is doing a lot of heavy lifting here. LLMs lack any mechanism for true logical reasoning, and they always will by nature. This is why they fail at simple questions like “the car wash test”. It’s also why agents are expensive; They just flail around in token hungry “reasoning loops” until they happen to come across a correct solution. And it’s why Claude Opus 4.8 (High) only scores 1.5% on the ARC-AGI-3 benchmark at a cost of $10,000.
This kind of panic is just part of the hype. Wake me up when real intelligence arrives.

I like Ed, but not a fan of this style of teasing. Reminds me of conspiracy theory communities. We’ll see what he has I guess.
I dunno, seems like an honest editing mistake that is actually more likely to be human than AI generated. Probably should read “In particular in the last six months, but two things have changed dramatically over the last twelve months.”
Not to diminish your frustration, but the scary thing about this is that it’s happening in the workplace by professionals on a daily basis now. People have absolutely just surrendered all of their thinking abilities. What an absurd world. I wish I could be more certain about the bubble bursting, but we may have to live with the AI overview zombies for a while.
Fortunately, I don’t think the judge will ask them to do that.
I don’t understand this form factor. It’s too small for any serious work, both in terms of screen size and typing, and it’s too big to fit in your pocket. So you might as well carry a small laptop around, since it would actually be usable. Feels like a novelty that is just meant to satisfy a cyberpunk aesthetic, if you’ve got the money to burn on something that you’ll probably only use a few times, or occasionally at best.
I just wanted to avoid linking directly to LinkedIn, since I think people would rather avoid visiting it for various reasons. I prefer linking to archives though, since copy-pasting feels more like theft of someone else’s content. At least the archive maintains the original context and authorship. Wikipedia basically uses archive.org as their main archive, so I don’t think a lemmy post will affect their load.
The Luddites didn’t hate machines. They were gifted artisans resisting a capitalist takeover of the production process that would irreparably harm their communities, weaken their collective bargaining power, and reduce skilled workers to replaceable drones as mechanized as the machines themselves. Their struggle has been tragically warped into a caricature when it is more relevant than ever.
https://www.currentaffairs.org/news/2021/06/the-luddites-were-right
Google recommends having 22 GB of space available, though the Nano (v3Nano) model for desktop use is ~4.27 GB.
Though I assume they download it on demand, or in the background after the initial install.

Bless uncle Bernie, but the US is in no state to even consider this. It has installed capitalism as its king.